

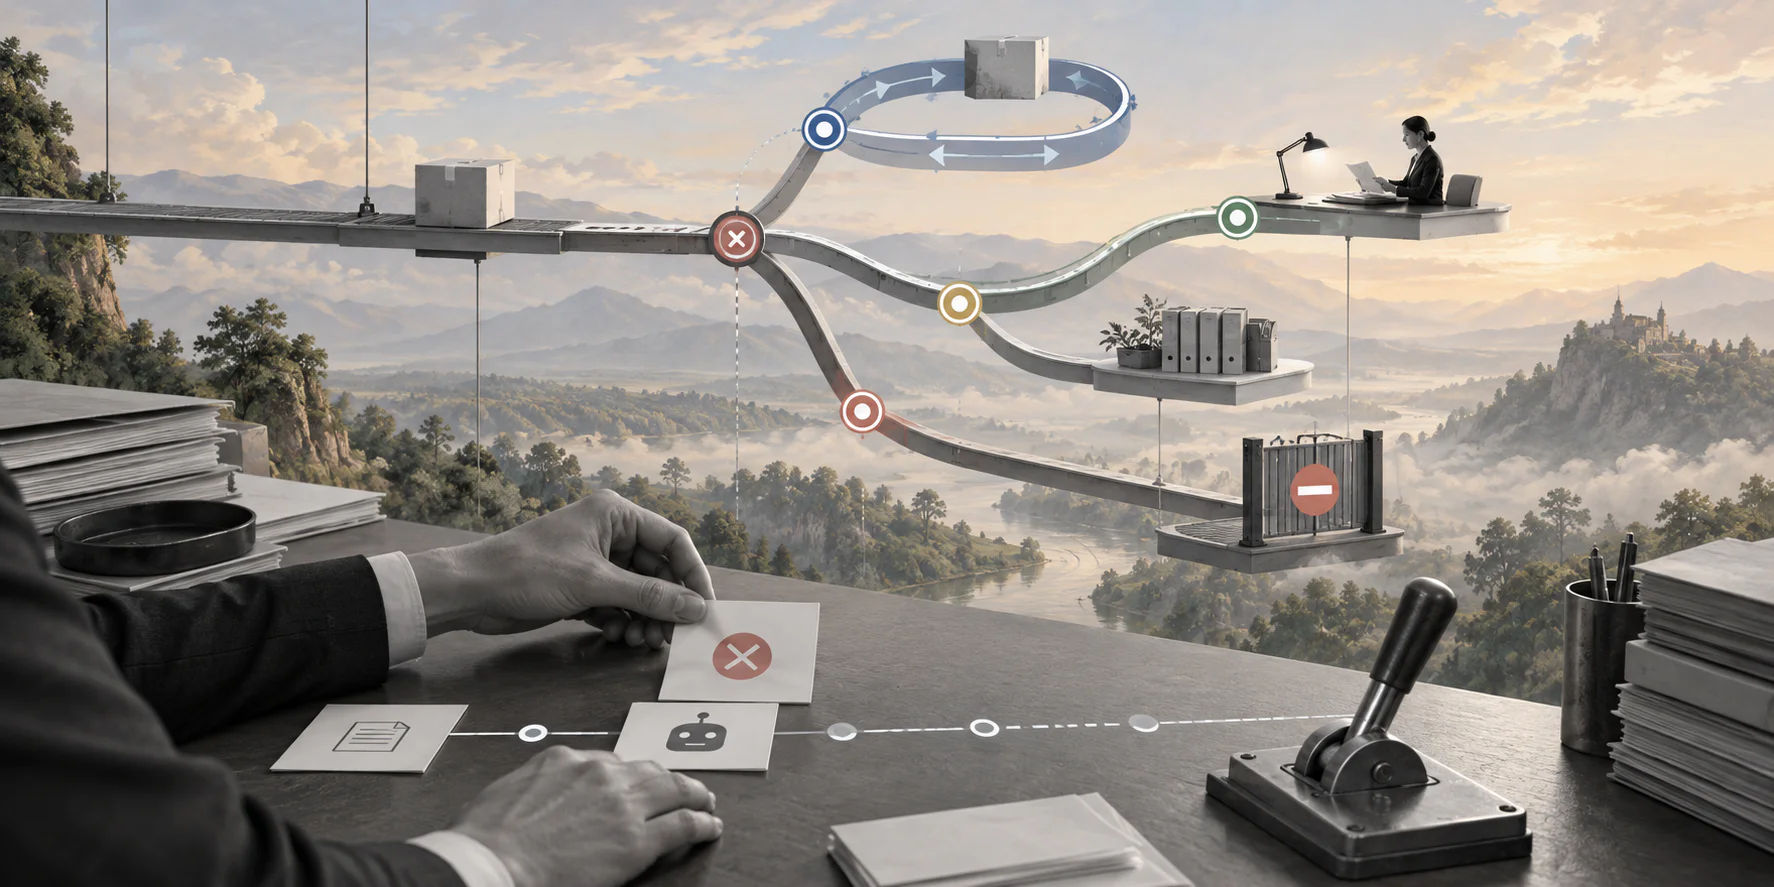
AI automation becomes safer when failure has a designed path before production work depends on it.
AI workflow fallback strategy is the operating plan for what happens when an AI-assisted workflow cannot safely continue. It defines when to retry, when to switch models or routes, when to return partial work, when to ask a person, and when to stop before the automation creates duplicate actions, bad records, compliance exposure, or customer confusion.
Quick answer
An AI workflow fallback strategy should classify failures, set retry limits, preserve workflow state, route risky cases to human review, and record every fallback decision. The goal is not to hide AI failure. The goal is to keep business work moving safely when a model, prompt, data source, integration, approval, or downstream system does not behave as expected.
Why AI workflow fallback strategy matters
Traditional automation usually fails predictably: a rule misses, an API times out, or a required field is missing. AI workflow automation adds more fluid failure modes. A model may produce malformed output, miss source evidence, classify a case with low confidence, choose the wrong tool, or recommend an action that is technically possible but operationally unsafe.
The NIST AI Risk Management Framework frames AI risk management as a lifecycle activity, not a one-time launch checklist. For workflow automation, that means recovery paths should be designed before the AI touches customer records, employee data, vendor approvals, payment steps, compliance records, or public communication.
Security guidance points in the same direction. The OWASP Top 10 for LLM Applications highlights prompt injection, sensitive information disclosure, and excessive agency. Fallback strategy helps prevent those risks from becoming silent workflow actions.
What is an AI workflow fallback strategy?
An AI workflow fallback strategy is a set of rules and operating paths for recovering from AI, integration, data, or review failure inside a business process. It is broader than model failover. Model failover asks, “Which model should handle the request next?” Workflow fallback asks, “Is it still safe for this work item to continue, and who owns the next step?”
That distinction matters because some failures are safe to retry and others are not. A transient provider timeout before any tool call may be replayable. A failed payment update, external email, permission change, or record deletion may require reconciliation before any retry.
AI workflow fallback strategy checklist
Use this checklist before moving an AI-assisted workflow into production.
- Define the workflow boundary: name what the AI can read, draft, recommend, update, approve, or never touch.
- Classify failure types: separate model errors, validation errors, missing evidence, conflicting data, policy boundaries, integration failures, and human-review delays.
- Set retry rules: define which failures may retry, how many attempts are allowed, and when retry stops.
- Protect side effects: use idempotency keys and reconciliation checks before replaying work that may have changed another system.
- Create human review paths: route high-risk uncertainty to an owner with the input, AI output, evidence, failure reason, and clear actions.
- Record fallback evidence: store the reason, route, owner, outcome, affected system, and final decision.
Fallback decision table for business workflows
| Failure type | Safe fallback | What to record |
|---|---|---|
| Provider timeout before action | Retry with a limit or use approved equivalent route | Attempt count, error, route, latency, final result |
| Malformed structured output | Repair once, validate schema, then route to review if still invalid | Validation errors, repair prompt version, accepted fields |
| Missing source evidence | Narrow retrieval, return unsupported status, or ask a reviewer | Sources searched, missing field, evidence requirement |
| Conflicting system records | Pause and route to the system owner or process owner | Candidate values, source systems, owner decision |
| Possible side effect already started | Stop, reconcile external state, then resume or close manually | Operation ID, external status, reconciliation result |
| High-risk decision uncertainty | Require human approval before continuing | Risk reason, reviewer, decision, audit trail |
How to design fallback paths step by step
1. Start with business impact
Rank workflow steps by what happens if the AI is wrong. A low-risk summary can often fail softly. A vendor approval, payroll correction, access grant, payment release, or customer commitment needs stronger fallback controls.
2. Separate retry from review
A retry is useful for temporary technical failure. Review is useful for judgment, missing context, policy conflict, or risk. Do not send every technical timeout to a person, and do not retry operational ambiguity until the system guesses correctly.
3. Make model fallback conditional
Switching models can help with outages, rate limits, or capability gaps, but it can also change output quality, tool behavior, cost, and data handling. Use model fallback only when the alternate route satisfies the same task contract, output format, privacy requirements, and approval policy.
4. Design the human handoff
Microsoft’s documentation for multistage approvals in agent flows shows the operating pattern clearly: AI and human stages can work together, with conditions controlling whether work continues, rejects, routes, or requires final review. Human review works when the reviewer receives context, a clear decision, and a defined next step.
5. Instrument the fallback
Fallback paths should show up in logs, dashboards, and workflow records. The OpenTelemetry semantic conventions for generative AI systems are one example of model-call observability. Business teams need the operational layer too: which work item paused, who owns it, why it paused, and whether it was resolved.
Common mistakes
The first mistake is treating fallback as “try another model.” That may fix availability, but it does not prove the new output is safe, compliant, affordable, or consistent with the workflow contract.
The second mistake is hiding retries. If the system silently tries five times, leaders cannot tell whether the workflow is reliable or just expensive. The third mistake is routing cases to humans without enough context.
The fourth mistake is ignoring partial state. If an AI workflow has already drafted a message, updated a field, or called a tool, the fallback path must know what happened before deciding what is next.
Where Workhint fits
Workhint fits around the AI model as the configurable work system for fallback operations. The AI can classify, extract, summarize, recommend, or draft. Workhint helps structure the business process around that output: intake, roles, permissions, assignments, approvals, documents, schedules, payment steps, reporting, audit history, and automation rules.
For an AI workflow automation rollout, Workhint can help teams define fallback owners, create review queues, route exceptions by role or impact, preserve evidence, track SLA status, and report recurring failures. That makes fallback a managed workflow instead of a set of side conversations.
FAQ
What is the difference between AI fallback and AI failover?
Failover usually means routing a request to another provider, model, region, or service after a technical failure. Fallback is broader. It includes retries, partial output, human review, reconciliation, safe stop states, and manual recovery paths.
When should an AI workflow stop instead of retrying?
Stop when a retry could duplicate a side effect, bypass a policy control, send an external message twice, change a record incorrectly, or continue without required evidence. In those cases, reconcile state or require review before continuing.
Should every AI workflow have a human fallback?
Every high-impact AI workflow should have a human fallback. Low-risk read-only workflows may use safe messages, cached responses, or limited retries, but workflows affecting money, access, compliance, customers, vendors, or employee records need a clear review path.
Who owns AI workflow fallback strategy?
The business process owner should own the fallback standard, with support from operations, IT, security, legal, compliance, and engineering. Technical teams can implement the controls, but the business must define acceptable outcomes and escalation rules.
Conclusion
AI workflow fallback strategy is where automation becomes operationally trustworthy. A good fallback design does not pretend failure will disappear. It defines what each failure means, which routes are safe, who owns the next step, what evidence must be kept, and how the workflow improves after every exception.
Leave a Reply