

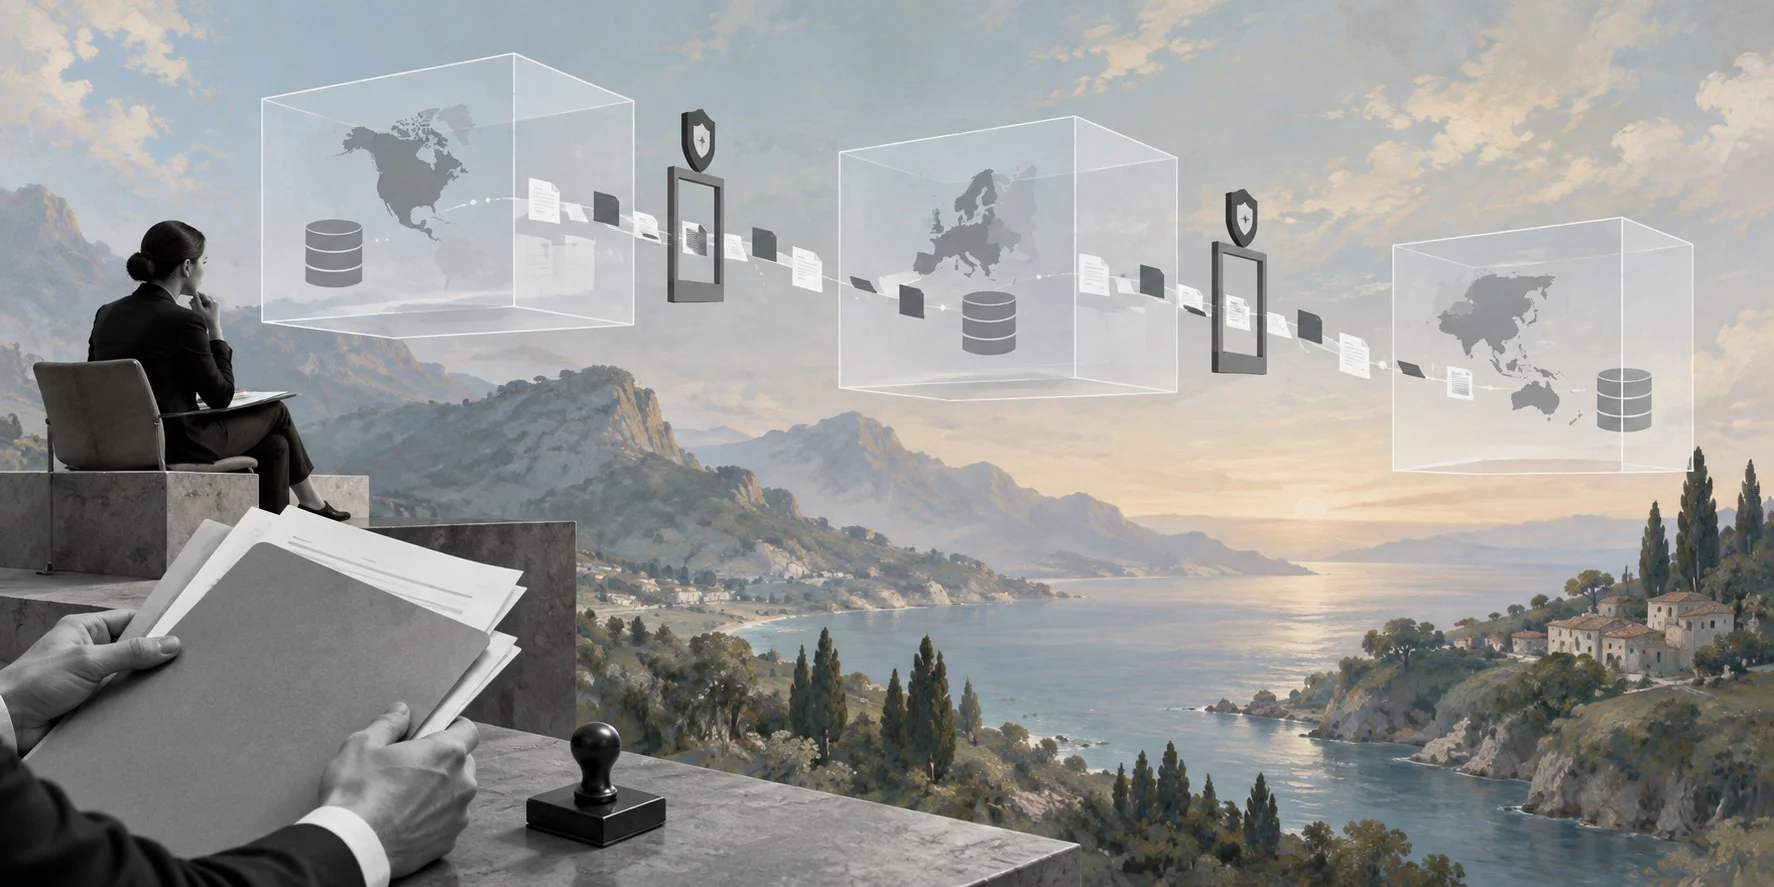
AI data residency becomes practical only when teams map where workflow data is stored, processed, reviewed, and retained.
AI data residency is the discipline of controlling where AI workflow data is stored, processed, and retained. For business teams, the risk is not only which model answers a prompt. It is whether customer records, employee data, vendor documents, financial details, or regulated files move through regions and systems the company never approved.
Quick answer
AI data residency for business workflows means defining where prompts, source documents, embeddings, outputs, logs, approvals, and audit records live. A practical setup maps each workflow data type, chooses region-aware AI and automation services, limits what leaves the business system, routes sensitive cases for review, and keeps enough evidence to prove what happened without retaining unnecessary data.
What’s in this article?
- What AI data residency means in operational workflows.
- How to map storage, processing, logs, and approval records.
- A practical checklist for business, IT, security, and operations teams.
- Where Workhint fits when AI needs to become governed workflow automation.
Why AI data residency matters in workflows
AI workflow automation increasingly touches operational data: contracts, invoices, tickets, onboarding records, supplier forms, staff schedules, payment information, and customer notes. Data residency becomes important when that information is stored or processed across countries, clouds, AI providers, automation tools, vector databases, ticketing systems, and logs.
The practical question is simple: can the company explain where every meaningful copy of the data goes? Google Cloud’s Gemini Enterprise Agent Platform data residency documentation distinguishes between data stored at rest and where model processing happens. Anthropic’s regional compliance page makes a similar point by separating storage residency from inference residency. Those distinctions matter because a workflow may satisfy one requirement while still failing another.
NIST’s Privacy Framework frames privacy work as identifying and managing privacy risk while enabling useful products and services. For AI workflows, that means residency should be treated as part of process design, not as a contract checkbox reviewed after the automation is already live.
AI data residency workflow map
Start by mapping the workflow from intake to final record. Do not map only the AI prompt. The workflow may create temporary files, embeddings, summaries, tool calls, approval notes, error logs, retry queues, dashboard metrics, and retained audit records.
| Workflow layer | Residency question | Control to define |
|---|---|---|
| Source data | Where do forms, files, records, and messages originate? | Approved source systems, data owner, sensitivity, region |
| AI processing | Where does inference or extraction happen? | Provider, endpoint, processing region, model policy |
| Temporary context | Are prompts, retrieved chunks, or files cached? | Retention setting, deletion window, prompt minimization |
| Workflow actions | Which systems receive the AI output? | Allowed tools, write permissions, approval gates |
| Logs and audits | Where are run logs, approvals, and exceptions stored? | Audit region, access rules, redaction, retention |
Step-by-step AI data residency checklist
- Name the workflow and business owner. Residency decisions should attach to a real process, such as vendor onboarding, invoice exception review, support escalation, recruiting intake, or contract analysis.
- Classify the data before AI sees it. Mark customer, employee, financial, health, legal, contractor, vendor, confidential, and public data differently. The workflow does not need every field just because the model can accept it.
- Separate storage from processing. Confirm where data is stored at rest and where inference, embeddings, document parsing, and tool execution happen. These may not be the same.
- Limit prompt payloads. Send the smallest useful context: selected fields, excerpts, references, masked values, or summaries instead of full records when possible.
- Control downstream actions. An AI output should not automatically update a customer record, approve spend, change access, or send an external message unless the workflow has explicit authority and review rules.
- Design the audit record intentionally. Keep enough evidence to reconstruct the workflow without storing unnecessary sensitive text forever. Record requester, record type, AI task, model or service, reviewer, approval, action, timestamp, and exception reason.
- Review the full vendor chain. AI providers are only one part of the chain. Check automation tools, data warehouses, vector databases, file stores, observability platforms, and support systems.
Practical example: vendor risk review
Consider a procurement team using AI to prepare vendor risk reviews. The workflow receives a supplier form, security questionnaire, tax document, insurance certificate, contract draft, and business justification. AI can extract fields, summarize security answers, identify missing evidence, and recommend a risk route.
The residency design should decide which documents may leave the vendor management system, whether the model endpoint stays in an approved region, whether extracted text is stored in a vector database, who can view finance or bank data, where approval notes live, and how long logs remain. If a supplier serves EU customers, legal and security may require tighter controls than for a low-risk domestic office vendor.
Common AI data residency mistakes
- Checking only the model provider. Workflow data may also live in automation logs, file stores, embeddings, dashboards, and error queues.
- Confusing no training with residency. A provider may say data is not used for training while still processing or retaining it in a region the company needs to review.
- Retaining raw prompts forever. Internal logs can create more exposure than the AI call itself if full sensitive prompts are kept unnecessarily.
- Letting summaries bypass permissions. A user who cannot view a source document should not automatically gain access to its sensitive content through an AI summary.
- Ignoring exceptions. Failed runs, retries, support tickets, and manual recovery steps often create extra copies of data.
Where Workhint fits
Workhint fits around the AI model as the workflow and governance layer. A model may summarize a document, classify a request, extract vendor fields, or recommend a next action. Workhint helps teams build the operational system around that intelligence: intake, roles, permissions, assignments, approvals, documents, schedules, payments, reporting, automation, and audit records.
For AI data residency, that operating layer matters because residency is not only a provider setting. The workflow must decide which data is collected, which fields are sent to AI, who can view summaries, where approvals happen, which records remain, and how exceptions are routed. For teams evaluating workflow automation software, the strongest question is whether the system can make AI-assisted work controlled, permissioned, and auditable across the full process.
FAQ
What is AI data residency?
AI data residency is the control of where AI-related data is stored, processed, logged, and retained. In workflows, it applies to prompts, documents, extracted fields, embeddings, model outputs, approvals, and audit records.
Is data residency the same as zero data retention?
No. Data residency is about location. Zero data retention is about whether a provider retains eligible prompts or outputs after processing. A workflow can need both controls, but they solve different problems.
Who should own AI data residency decisions?
The business process owner should own the workflow outcome, while IT, security, legal, privacy, compliance, and data teams should define residency, access, retention, and review requirements.
Do all AI workflows need strict residency controls?
No. Public or low-risk internal workflows may need ordinary privacy and access controls. Sensitive workflows involving customer, employee, financial, legal, health, vendor, or regulated data need stronger review.
What should teams check before launch?
Check source systems, AI processing region, storage region, temporary files, embeddings, logs, review records, downstream tools, support access, deletion windows, and exception handling.
Conclusion
AI data residency works when it is built into the workflow before automation scales. Map the data path, classify the records, separate storage from processing, minimize what the model sees, control downstream actions, and keep the right audit evidence. That gives business teams a practical way to use AI in real operations without losing control of where sensitive work data goes.
Leave a Reply