
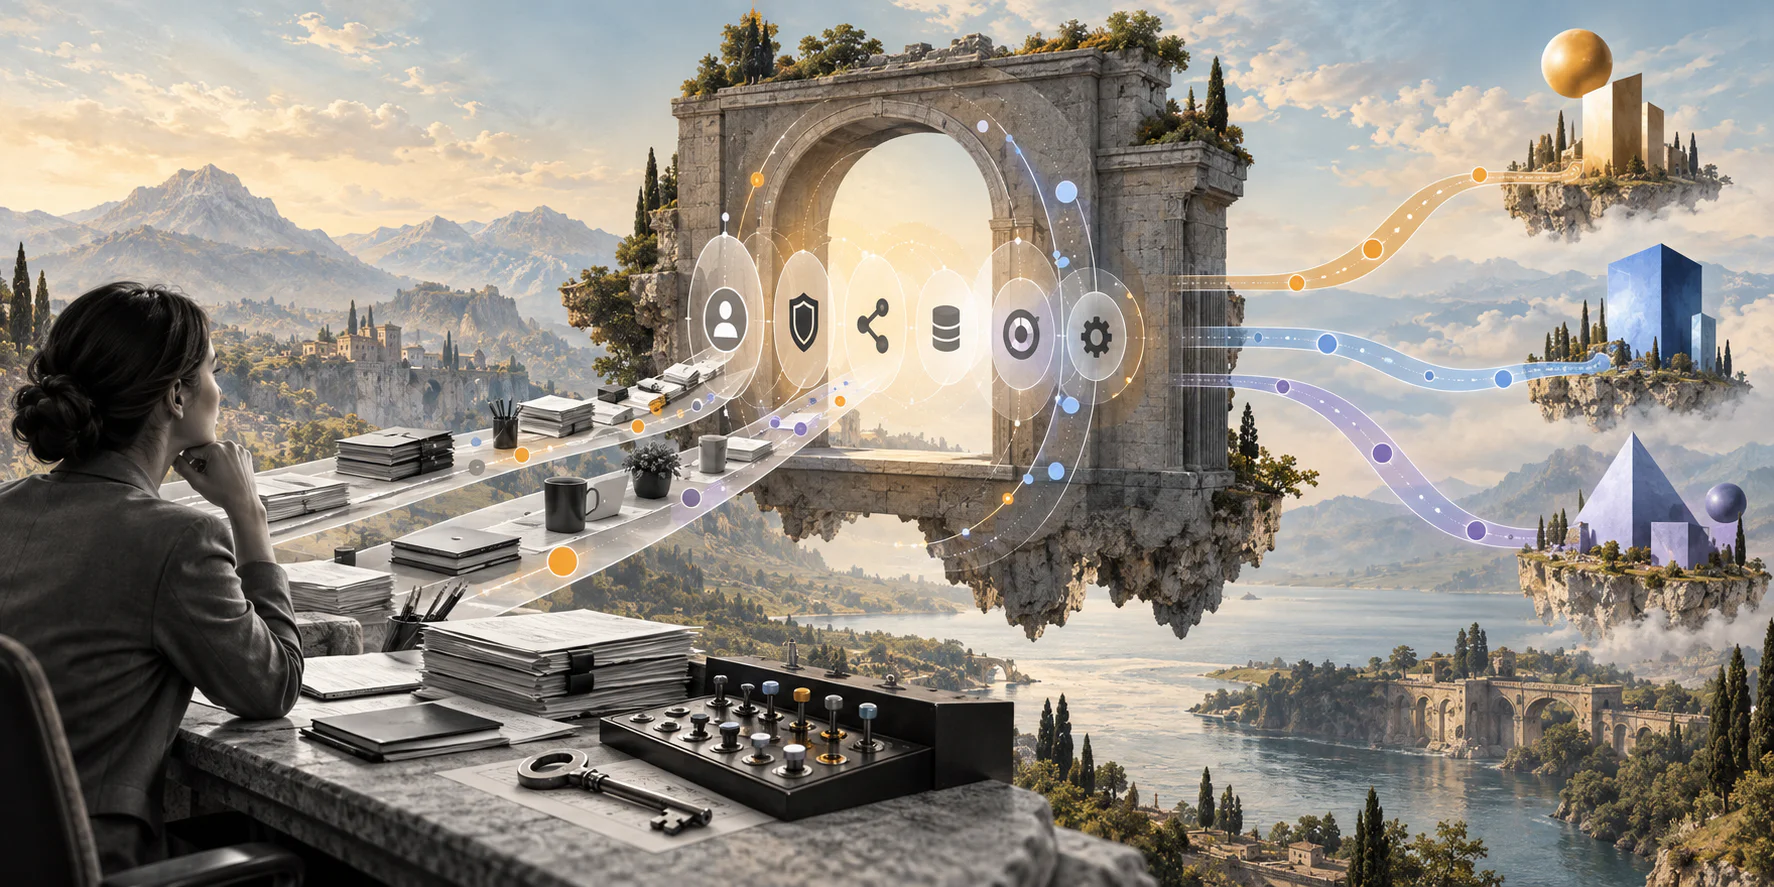
One gateway can turn scattered model integrations into a controlled, observable, and resilient business capability.
LLM gateway architecture gives a business one governed path between its applications and multiple AI model providers. Instead of every team managing credentials, retries, budgets, logging, and safety controls independently, the gateway applies shared policies before requests reach a model and before responses return to a workflow.
Quick answer
An LLM gateway is a control layer between business applications and AI models. A sound architecture centralizes identity, request policies, model routing, fallbacks, budgets, observability, and response checks. Start with one narrow workflow, keep business approvals outside the gateway, and instrument every request so teams can trace cost, latency, errors, and outcomes.
What’s in this article?
- The business case for an LLM gateway
- A seven-layer reference architecture
- A practical implementation sequence
- Tradeoffs, mistakes, and ownership decisions
- How the gateway connects to operational workflow orchestration
Why does an LLM gateway matter?
Direct model integrations are easy to start and hard to govern. A support team may call one provider, finance another, and an internal agent a third. Each integration then develops its own authentication, error handling, prompt logging, and cost controls. Provider changes multiply that work.
Current gateway platforms reflect this demand. Cloudflare documents analytics, logging, caching, rate limiting, retries, and model fallback. Portkey’s gateway documentation adds conditional routing, circuit breakers, budget limits, and provider abstraction. These are not business workflow features; they are shared infrastructure controls that make model access safer and easier to operate.
What is an LLM gateway architecture?
An LLM gateway architecture places a policy-aware proxy between AI-enabled applications and approved model endpoints. Applications send a consistent request to the gateway. The gateway authenticates the caller, evaluates policy, selects an allowed model, records telemetry, handles predictable failures, and returns a filtered response.
The gateway should not decide whether an invoice is paid, a candidate is rejected, or a vendor is approved. Those are business decisions that belong in a workflow system with roles, permissions, records, and human accountability.
The seven layers of an LLM gateway architecture
| Layer | Primary control | Operational question |
|---|---|---|
| Identity and access | Authenticate apps, users, and service accounts | Who may call which model? |
| Request policy | Validate size, data class, and allowed use | Can this content leave the workflow? |
| Routing | Select a model by task, risk, region, and cost | Which approved endpoint fits this request? |
| Resilience | Apply timeouts, retries, circuit breakers, and fallback | What happens when a provider fails? |
| Cost control | Enforce token, request, and team budgets | How much may this workflow spend? |
| Observability | Capture traces, errors, latency, usage, and versions | Can the team explain what happened? |
| Response policy | Check format, sensitive data, and safety rules | Is the output safe and usable downstream? |
Kong’s AI Gateway documentation similarly frames the gateway as a connectivity and governance layer spanning authentication, policy enforcement, routing, security, and observability. For portable telemetry, teams can align trace fields with the OpenTelemetry generative AI semantic conventions rather than inventing provider-specific logs.
How do you design an LLM gateway?
- Inventory model calls. Record the workflow, owner, data classification, model, volume, latency target, and downstream action for every current integration.
- Define the gateway boundary. Route model inference through the gateway, but keep document systems, business records, approvals, and payment actions in their owning platforms.
- Choose a stable request contract. Standardize identity, task type, data class, model policy, timeout, correlation ID, and expected response schema.
- Set policy before routing. Reject unauthorized callers or prohibited data before selecting a provider. Routing must never bypass access rules.
- Design explicit failure paths. Decide which errors permit retry, which allow a lower-risk fallback, and which must stop for human review.
- Instrument the full path. Capture application, workflow, gateway, provider, model version, token usage, latency, error class, and final disposition without logging sensitive content unnecessarily.
- Pilot one bounded workflow. Compare reliability, cost, review volume, and completion time against the previous process before expanding.
Practical example: supplier document review
A procurement workflow receives supplier documents and asks an LLM to extract expiration dates, insurance limits, and missing fields. The workflow authenticates to the gateway using a service identity and labels the request as confidential procurement data. The gateway permits only approved regional endpoints, applies a spend limit, enforces a structured response schema, and records a trace ID.
If the primary model times out, the gateway retries once and then uses an approved fallback. If extraction confidence is low or required fields conflict, the workflow routes the case to a procurement reviewer. The gateway handles model traffic; the workflow owns the supplier record, review queue, approval, reminders, and audit history.
What tradeoffs should teams evaluate?
- Central control versus bottlenecks: one gateway simplifies governance but needs high availability, capacity planning, and a clear platform owner.
- Abstraction versus provider features: a common API reduces switching costs, but the lowest common denominator can hide valuable provider-specific capabilities.
- Visibility versus privacy: detailed logs improve debugging, yet prompts and responses may contain confidential information. Redact, minimize, and set retention deliberately.
- Fallback versus consistency: another model may keep work moving, but its output quality and format can differ. Test fallbacks against the same acceptance criteria.
Common LLM gateway mistakes
Do not treat a gateway as a complete AI governance program. It cannot fix unclear workflow ownership, weak source data, or missing approval rules. Avoid silent model switching, unlimited retries, shared credentials, raw prompt logging by default, and routing solely by price. The gateway configuration itself also needs version control, staged rollout, and rollback.
Where Workhint fits
An LLM analyzes or generates content, while the gateway controls access to that model. Workhint sits at the operational layer around both. With configurable AI workflow automation, an organization can connect intake, roles, permissions, assignments, documents, approvals, schedules, payments, reporting, and escalation paths. The gateway returns a governed AI result; Workhint routes the related work, preserves the business record, and keeps people accountable for consequential actions.
FAQ
Is an LLM gateway the same as an API gateway?
No. An LLM gateway uses API gateway patterns but adds model-aware controls such as token budgets, model routing, prompt and response policy, semantic caching, and AI-specific telemetry.
When does a business need an LLM gateway?
Consider one when several applications or teams call AI models, when multiple providers are used, or when shared security, budget, resilience, and audit controls have become difficult to maintain separately.
Should every AI request use a fallback model?
No. Use fallbacks only when the alternative model is approved and tested for the same task. High-risk actions may need to stop and enter human review instead.
What should an LLM gateway log?
Log caller identity, workflow and request IDs, policy decision, provider, model version, latency, token usage, error class, and response disposition. Minimize or redact prompt and response content based on data policy.
Conclusion
A useful LLM gateway is more than a model proxy. It is a shared control layer for identity, policy, routing, resilience, cost, observability, and response safety. Start with a bounded workflow, keep business decisions in the workflow system, test failure paths, and expand only when the evidence shows better control without creating a new central bottleneck.
Leave a Reply