
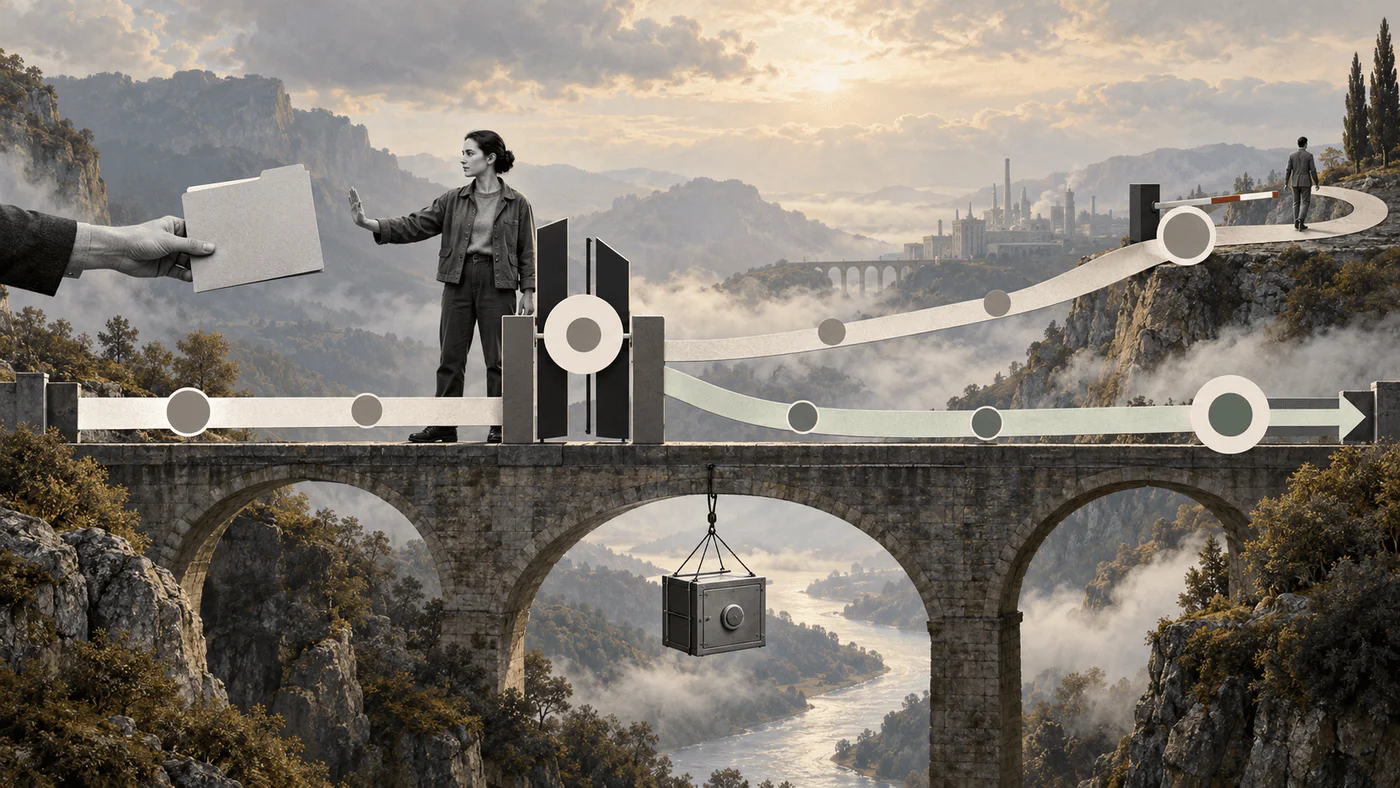
An AI agent outage should not turn into a business-process outage. If an agent helps route customer requests, review documents, create records, or trigger approved actions, the team needs a tested way to keep the work moving when the model, tool layer, identity provider, or orchestration service is unavailable.
An AI agent disaster recovery runbook is that operating plan. It does not ask an AI system to improvise a recovery. It defines the outage trigger, the state to preserve, the manual lane, the bounded recovery actions, the approval gates, and the evidence required before the workflow returns to automation.
Quick answer
Build an AI agent disaster recovery runbook around the business workflow, not the model alone. Define the switch-to-manual trigger; snapshot the workflow’s intent, state, and side effects; use deterministic, idempotent recovery actions; require a human approval before consequential re-entry; reconcile every in-flight item; and rehearse the plan against a real failure scenario.
Why an agent recovery runbook is different
Conventional disaster recovery often focuses on restoring infrastructure. That remains important, but an agent-dependent workflow has another question: what business work was in progress, and what did the system already do? A customer request may have been classified but not assigned. A payment exception may have been reviewed but not submitted. A vendor record may have been created just before a worker failed.
Restarting a service does not answer those questions. An operational runbook has to distinguish between a reversible recommendation and an external side effect such as sending a message, changing a record, or releasing an approved payment. It should preserve an execution ID, the current state, the evidence used, the action request, and the outcome of each system call. That record lets an operator resume safely instead of guessing or doing the work twice.
AWS guidance for agentic systems makes the same separation: recovery-safe checkpointing depends on idempotent steps, while manual fallback procedures need explicit triggers, owners, and independently accessible runbooks. In other words, AI can interpret an incident, but rules and systems must control recovery.
The production boundary: who does what
| Responsibility | Owner during recovery | Example |
|---|---|---|
| Interpret the incident evidence | AI, with human review when confidence is low | Summarize a failed order-routing pattern and the affected queues. |
| Detect a known failure condition | Deterministic monitoring | Error rate exceeds the documented threshold for the documented interval. |
| Authorize a consequential action | Named human role | Approve re-entry after a customer-facing workflow has been paused. |
| Execute a permitted recovery step | System integration with policy checks | Resume an existing job using its original idempotency key. |
| Persist the recovery record | Workflow system | Store the incident, approval, action result, and reconciliation status. |
This boundary prevents two common mistakes: treating model output as a command, and asking people to reconstruct workflow state from chat messages after an outage.
The AI agent disaster recovery runbook canvas
For each critical workflow, maintain one short, operator-usable record. The following canvas is a starter map to validate against your systems; it is not a substitute for security, legal, or incident-response requirements.
- Scope and owner: Name the workflow, accountable business owner, technical owner, affected roles, and the manual system of record.
- Activation trigger: State measurable conditions for pausing automation, such as a failed health check, unavailable dependency, invalid-output rate, or a specified error threshold. Include who can declare the incident.
- State snapshot: Preserve the workflow ID, input reference, current state, model/prompt version when relevant, attempted actions, external-operation IDs, and approval status. Reference sensitive source data instead of copying it into an incident channel.
- Manual continuity lane: Specify the intake queue, owner, priority rules, required evidence, and completion record. The manual path must work when the agent platform is unavailable.
- Recovery classes: Mark each step as safe to retry, reconcile-first, human-approved, or prohibited. An action that can create an external side effect is never simply “retry.”
- Re-entry conditions: Require a dependency check, a sample validation, reconciliation of in-flight work, approval, and a defined monitoring window before restoring normal automation.
- Drill evidence: Record the scenario, start and end times, gaps found, operator feedback, and the owner/date for the next revision.
Example: recovering a supplier-onboarding workflow
Consider an agent that extracts supplier details from an intake packet, checks required fields, and prepares a record for an operations reviewer. The agent service becomes unavailable after the extraction result is stored but before the reviewer task is created.
The runbook should move the affected intake IDs to a manual queue, not ask the agent to rerun blindly. The operator first checks whether a supplier record or reviewer task already exists. If neither exists, the system can create the missing task from the preserved extraction result. If the record exists but its status is unknown, the operator reconciles it against the external record before proceeding. The original workflow ID remains attached throughout.
When service is restored, a small sample of paused cases should run through validation in a controlled state. Only after the business owner approves the reconciliation report should the workflow resume. That sequence protects against the two costly failure modes: losing a real request and processing one twice.
Design recovery states before an outage
Use explicit states rather than a vague “failed” label. A practical lifecycle might be:
active → paused → snapshot-confirmed → manual-processing or recovery-running → reconciled → re-entry-approved → active
Every transition needs a condition and an owner. For example, paused is entered by a documented monitor or incident commander; snapshot-confirmed is entered only when the state store and external-action ledger agree; re-entry-approved requires the named business approver. If a tool is unavailable, a state cannot advance merely because a model recommends it.
For retryable work, use the same operation key on a restart and make the receiving system return the previous completed result when it has one. Read AI Workflow Idempotency for Business Automation for the underlying design. For items that still cannot complete after bounded attempts, use a recovery queue with context and replay controls rather than leaving them invisible; the dead-letter queue pattern for AI workflows explains that lane.
Make the manual lane usable
A manual fallback is only real if operators can access it during the failure. Keep the runbook, contact roles, minimal forms, and source-of-truth location independent of the failed agent service. Give operators a concise decision rule: what to do now, what not to do, where to record the outcome, and when to escalate.
Do not turn the manual lane into an unbounded spreadsheet. Use the same stable case ID, track the owner and decision, attach approved evidence, and record any external action. Those records become the reconciliation input once automation returns. For more detail on assigning uncertain cases to a named owner and deadline, see the AI agent escalation matrix.
Test recovery with a drill, not a promise
Run a tabletop exercise before production dependence is high, then periodically test a controlled interruption. Pick one scenario: a model-provider outage, an authorization failure, an unavailable tool, corrupted context, or a partial downstream write. Walk the team through the trigger, manual intake, state snapshot, reconciliation, approval, and re-entry.
- Can an operator find the runbook without the agent platform?
- Can the team identify every in-flight case and its last known side effect?
- Can the manual lane meet the business priority and response-time target?
- Can the system prove which cases are safe to replay?
- Does a named person approve the return to automation?
Capture the result as operational evidence, not a one-time compliance exercise. If a drill reveals a missing state record or an unclear owner, fix the workflow and test that exact gap again.
Where Workhint fits
Workhint can coordinate the operational recovery layer around an AI-assisted workflow: route the incident to the right owner, preserve the case and its approval history, create a manual-continuity queue, enforce re-entry approvals, and keep reconciliation evidence connected to the original work. It does not replace a model provider, an identity service, a system of record, or incident-response judgment.
For teams operating work across people, systems, approvals, and exceptions, Workhint’s workflow automation software can help keep the recovery path and normal workflow in one connected operational system.
Leave a Reply