
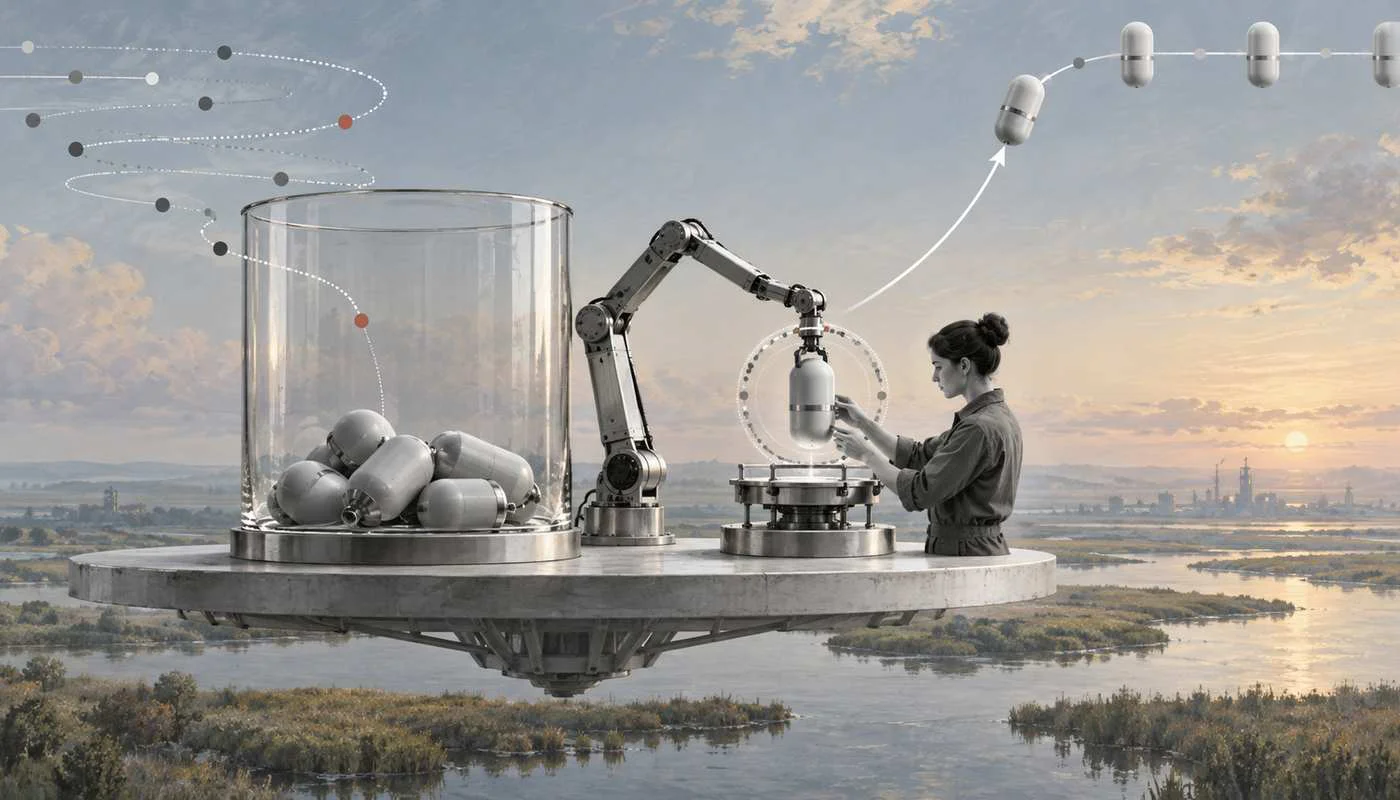
Retries keep work moving until the same bad task quietly becomes an operational incident.
Dead letter queues in AI workflows give failed tasks a controlled place to land after normal retries are exhausted. That matters because an AI step can fail for reasons a conventional worker never sees: malformed model output, missing context, a confidence score below policy, a blocked tool call, an expired approval, or a downstream API outage. A reliable design preserves the evidence, stops retry storms, assigns an owner, and supports safe replay.
Quick answer
Use a dead letter queue as a recovery lane for AI work that cannot complete after bounded retries. Store the task ID, failure reason, attempt history, model and prompt versions, safe input references, workflow state, and replay controls. Route each item to an owner, separate transient failures from permanent ones, and allow replay only after the cause is corrected and the action is idempotent.
What’s in this article?
- When an AI workflow needs a dead letter queue
- A practical failure taxonomy and message envelope
- A six-step recovery and replay process
- Metrics, mistakes, and an operating example
What is a dead letter queue in an AI workflow?
A dead letter queue, or DLQ, isolates work that a consumer could not process successfully. Amazon SQS describes DLQs as targets for messages that were not processed, allowing teams to inspect failures and later redrive messages. In an AI workflow, the same pattern should cover both technical errors and policy failures.
For example, a supplier-onboarding agent may extract banking details correctly but fail because the vendor record lacks an approved tax form. Repeated model calls will not fix that missing prerequisite. Moving the task to a recovery lane prevents wasted tokens and duplicate actions while giving an operations reviewer a clear case to resolve.
When should AI work move to the dead letter queue?
Define the routing rule before production. A useful policy distinguishes four failure classes:
| Failure class | Example | Default response |
|---|---|---|
| Transient | Rate limit, timeout, temporary API outage | Retry with backoff; dead-letter after the retry budget |
| Data | Missing field, corrupt document, unsupported format | Dead-letter and request correction |
| Policy | Confidence below threshold, approval required, restricted action | Route to human review without repeated inference |
| Permanent technical | Invalid schema, revoked permission, removed tool | Dead-letter, fix configuration or code, then test replay |
Do not set the delivery limit arbitrarily. AWS warns that a very low maximum receive count can move tasks before normal resilience has a chance to work. Conversely, unlimited retries hide poison messages and increase cost. Choose limits using the failure mode, task urgency, model cost, and downstream side effects.
How to design the dead letter queue workflow
- Give every task a durable identity. Use a workflow ID, task ID, tenant ID, and idempotency key so retries and replays cannot create duplicate records, approvals, payments, or messages.
- Preserve diagnostic context. Record timestamps, attempt count, failure code, tool response, model and prompt versions, schema version, and the workflow step. Store sensitive payloads by protected reference rather than copying secrets or unnecessary personal data into the queue.
- Use bounded, reason-aware retries. Retry timeouts and rate limits with backoff. Do not retry a missing document or denied permission as though it were a network glitch.
- Assign an operational owner. Map failure codes to engineering, operations, finance, HR, or another responsible team. Set a response target and escalate aged items.
- Require a replay gate. A reviewer or automated rule should confirm that the root cause is corrected, the destination is ready, and the action is safe to run again.
- Close the loop. Track the final disposition: replayed successfully, corrected manually, rejected, superseded, or quarantined. Feed recurring causes into prompt, schema, integration, and process improvements.
Azure Service Bus documentation notes that applications can attach a dead-letter reason and description, then let a user correct and resubmit the message. That operating pattern is more useful than a queue that merely accumulates failures.
What should the dead letter record include?
Keep the envelope consistent across models and tools. At minimum include the source workflow, failed step, correlation ID, idempotency key, failure class, machine-readable reason code, first and last failure time, attempt count, model or tool version, input reference, safe output excerpt, current owner, approval state, and replay status.
Retention and access also need explicit rules. AWS recommends keeping DLQ retention longer than the source queue, while Google Cloud Pub/Sub requires correct permissions for forwarding and describes delivery-attempt counts as approximate. Treat platform defaults as implementation details, not as your business control model.
Practical example for invoice exception handling
Consider an AI service that extracts invoice fields and proposes a general-ledger code. A valid invoice continues to approval. A model timeout gets two delayed retries. A low-confidence code goes directly to an accounts-payable reviewer. A malformed supplier record enters the DLQ with the vendor ID, validation error, document reference, and workflow state. After the vendor record is corrected, the reviewer approves replay. The idempotency key prevents a second invoice from being created.
The team monitors DLQ arrival rate, oldest-item age, recovery time, successful replay rate, repeat-failure rate, and failures by reason. Those measures reveal whether the problem is model quality, source data, permissions, integration reliability, or process design.
Common dead letter queue mistakes
- Treating the DLQ as permanent storage. Every item needs an owner, status, and disposition.
- Replaying in bulk without idempotency. A corrected queue can still create duplicate external actions.
- Storing full prompts and documents by default. Preserve diagnostic value while minimizing sensitive data.
- Ignoring order dependencies. AWS cautions that using a DLQ with FIFO work can break exact sequence requirements.
- Creating routing loops. RabbitMQ documents dead-letter cycles and cases where republishing can fail; test the failure path itself.
- Alerting on every single event. Use severity, volume, age, and business impact so alerts remain actionable.
Where Workhint fits
A broker or cloud queue transports failed messages; it does not run the full recovery operation. Workhint can provide the surrounding workflow automation software layer: create a review case, apply role-based permissions, assign the right owner, collect missing documents, route approvals, track service targets, record the resolution, and authorize controlled replay. The model still analyzes content and the queue still handles message delivery; Workhint coordinates the people, decisions, records, and audit trail around the exception.
Frequently asked questions
Is a dead letter queue the same as a retry queue?
No. A retry queue delays work that is expected to succeed later. A dead letter queue isolates work that exhausted its retry policy or needs correction, investigation, or approval.
How many times should an AI task retry?
There is no universal number. Use more attempts for short-lived network failures and fewer for expensive model calls or actions with side effects. Never retry permanent data or policy failures without a change in state.
Can failed AI tasks be replayed automatically?
Yes, when the cause is known, the fix is verifiable, and the action is idempotent. High-risk actions such as payments, access changes, or external communications should usually require human approval.
Who should own the dead letter queue?
Technical platform ownership may sit with engineering, but each failure class needs a business owner. Finance should resolve invoice exceptions; procurement should resolve supplier gaps; engineering should resolve schema or integration defects.
Conclusion
A dead letter queue is valuable only when it leads to recovery. Classify failures, preserve safe diagnostic context, assign owners, enforce replay controls, and measure outcomes. That turns failed AI work from an invisible retry loop into a manageable business process.
Leave a Reply